Large language models can write essays, summarize documents, translate languages, generate code, answer questions, and imitate many styles of human writing. From the outside, the experience can feel surprisingly conversational.
Inside the model, however, there is no miniature person reading and composing sentences. Instead, billions of numerical values work together to estimate what piece of text should come next.
A large language model is essentially a highly complex prediction system trained to recognize patterns in language and use those patterns to generate new sequences of tokens.
Understanding what happens inside a large language model reveals how modern artificial intelligence turns numbers into remarkably coherent language.
Text First Becomes Tokens
A language model does not directly process sentences as humans see them.
Before text enters the neural network, it is divided through tokenization.
A token may represent an entire word, part of a word, punctuation, or another commonly occurring text fragment. For example, an uncommon word might be split into several smaller components, while a frequent short word may remain a single token.
This approach allows a model to handle enormous vocabularies without storing every possible word as an independent item.
The model receives sequences of token IDs, not raw sentences.
Those IDs are then converted into mathematical representations that the network can process.
Words Become Coordinates in a Mathematical Space
Each incoming token is transformed into a vector through embeddings.
An embedding is a collection of numbers representing learned features of a token. During training, words and word fragments that occur in related contexts often develop useful mathematical relationships.
This does not mean the model stores a dictionary-style definition for every word.
Instead, meaning is distributed across many numerical dimensions.
For example, the model may learn that terms involving oceans, rivers, rain, and water frequently occur in overlapping contexts while still distinguishing their different roles.
These numerical representations allow language to be processed through mathematical operations.
The Transformer Processes Relationships Between Tokens
Most modern large language models are based on a neural-network architecture called the transformer.
Transformers became especially important because they can efficiently analyze relationships between many parts of a sequence.
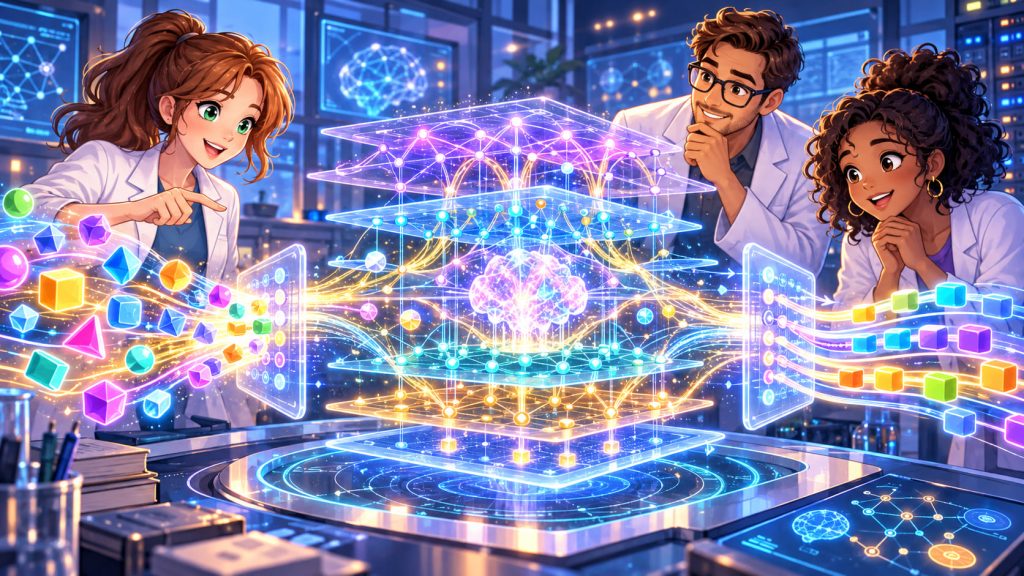
Inside a transformer, information passes through multiple layers. Each layer modifies the numerical representation of the text based on patterns learned during training.
A crucial mechanism is attention.
Attention allows the model to calculate how strongly one token should relate to other tokens in the available text.
Consider the sentence:
“The scientist placed the glass on the table because it was unstable.”
To understand what “it” probably refers to, the model must consider the relationships among several earlier words.
Attention helps build these contextual relationships across a sequence.
Attention Does Not Work Like Human Attention
The word “attention” can be misleading.
A model is not consciously deciding what deserves concentration.
Instead, mathematical operations calculate weighted relationships among token representations.
Different attention heads can learn different useful patterns. Some may become sensitive to grammatical structure, while others may help track long-distance relationships, formatting, names, or semantic associations.
These signals are repeatedly combined and transformed as information moves through the network.
The final representation of a token can therefore depend heavily on the tokens surrounding it.
Billions of Parameters Store Learned Patterns
The behavior of a neural network is controlled by numerical values known as parameters.
Large language models can contain billions or more of these adjustable values.
Parameters are not individual facts stored in clearly labeled locations. There is usually no single parameter containing the fact that Paris is the capital of France.
Instead, knowledge and linguistic patterns are distributed across large networks of interacting values.
This distributed representation is one reason interpreting large neural networks is difficult.
Researchers can often identify useful internal patterns, but completely explaining why a very large model produced one particular output remains a major scientific challenge.
How a Language Model Learns
The first major stage is typically pretraining.
During pretraining, a model processes enormous amounts of text and repeatedly practices predicting missing or next tokens.
Suppose the training sequence contains:
“Water freezes at zero degrees Celsius.”
The model might receive the sequence up to “zero degrees” and predict what follows.
Early predictions are poor.
A mathematical loss function measures the difference between the model’s prediction and the correct training target. An optimization algorithm then adjusts the model’s parameters slightly.
This happens again and again across enormous numbers of examples.
Over time, the model develops statistical representations of grammar, facts, styles, reasoning patterns, programming languages, and relationships between concepts.
Training Requires Backpropagation
Parameter adjustment occurs through a process known as backpropagation.
The system calculates how much each relevant parameter contributed to an error and propagates information about that error backward through the network.
An optimizer then changes the parameters in directions expected to reduce future errors.
Training modern models requires enormous amounts of computation because this process is repeated across huge datasets and very large neural networks.
Specialized processors such as GPUs and other AI accelerators perform massive numbers of matrix calculations in parallel.
Pretraining Is Only Part of the Process
A pretrained model can predict language but may not yet behave like a useful assistant.
Developers can apply fine-tuning using carefully selected examples to encourage particular behaviors or improve performance on specialized tasks.
Models can also be trained with forms of human or AI feedback so that useful, relevant, and safer responses become more likely.
This additional training does not replace the knowledge acquired during pretraining. Instead, it changes how the model uses its capabilities when responding to instructions.
What Happens When You Ask a Question?
When a trained model receives a prompt, it enters the process called inference.
First, the prompt becomes tokens.
The tokens are converted into embeddings and processed through many transformer layers. The network then produces scores for possible next tokens.
Those scores are converted into probabilities.
If the prompt is:
“The largest planet in the Solar System is”
the model may assign a very high probability to “Jupiter” compared with alternatives.
Once a token is selected, it is added to the sequence. The entire process continues repeatedly.
A generated answer is produced token by token.
The model does not normally create the complete paragraph first and then reveal it word by word.
Why Responses Can Be Different Each Time
Language generation often includes controlled randomness.
Instead of always selecting the single most probable next token, the system can sample among several plausible possibilities.
Settings such as temperature influence how concentrated or varied those choices are.
Lower randomness tends to produce more predictable responses. Higher randomness can increase variety but may also increase mistakes or unusual phrasing.
This is why the same prompt can produce different answers without the model having changed its underlying parameters.
The Context Window Acts Like Working Information
A model can only directly process a limited amount of information at once. This capacity is known as the context window.
It may contain the current prompt, earlier conversation, attached information made available to the model, and the response being generated.
Information outside that active context is not automatically available during that particular generation unless another system retrieves or supplies it.
Larger context windows allow models to work with longer documents and conversations, but they also increase computational demands.
Why Large Language Models Can Make Mistakes
A language model is optimized to generate plausible sequences, not to internally guarantee that every statement corresponds to reality.
This can produce hallucination: confident-looking text containing invented or incorrect information.
The problem occurs partly because fluent language generation and factual verification are different tasks.
Modern AI systems can reduce these errors through better training, reasoning methods, external tools, retrieval systems, and verification processes, but no general-purpose language model is perfectly reliable.
This is why important medical, legal, scientific, financial, and factual claims may require independent verification.
Expert Perspective: Understanding Models Remains an Open Science
AI researchers increasingly study a field called mechanistic interpretability, which attempts to identify how particular internal components and patterns produce model behavior.
Researchers have discovered internal features related to concepts, syntax, computation, and other behaviors, but understanding a modern model completely remains far beyond current capabilities.
Experts in interpretability generally emphasize that neural networks are not simply conventional software containing human-written rules.
Their behavior emerges from millions or billions of learned interactions.
We know the mathematical operations performed by a language model, but fully explaining everything represented inside a large trained network is much harder.
Interesting Facts
- Large language models process tokens rather than ordinary written words.
- A single word can consist of one token or several tokens depending on the tokenizer.
- Transformer models perform enormous numbers of matrix multiplications while generating text.
- Knowledge is distributed across many parameters rather than stored as a simple database of sentences.
- A model can produce an answer it has never encountered exactly before by combining patterns learned during training.
- The same model can generate different outputs from an identical prompt when probabilistic sampling is used.
- Longer context windows allow models to process larger documents, but they require additional computation and memory.
- Researchers can sometimes identify internal neural-network features associated with recognizable concepts, but complete interpretation remains extremely difficult.
Glossary
- Tokenization — The process of dividing text into smaller units called tokens before the model processes it.
- Embeddings — Numerical vector representations that encode learned information about tokens and their relationships.
- Transformer — A neural-network architecture designed to process sequences using attention and other mathematical operations.
- Attention — A mechanism that calculates relationships between different tokens in a sequence.
- Parameters — Adjustable numerical values inside a neural network that store learned patterns.
- Pretraining — The large-scale initial training stage in which a model learns statistical patterns from extensive data.
- Backpropagation — A training method that calculates how model parameters contributed to prediction errors so they can be adjusted.
- Fine-Tuning — Additional training used to adapt a pretrained model to particular behaviors, tasks, or domains.
- Inference — The process of using a trained model to generate predictions or responses.
- Context Window — The limited amount of information a model can directly consider during a single processing sequence.
- Hallucination — A generated statement that sounds plausible but is unsupported, invented, or factually incorrect.
- Mechanistic Interpretability — Research aimed at understanding how internal components of neural networks produce specific behaviors.